Topic: run
18 stories found
Yesterday
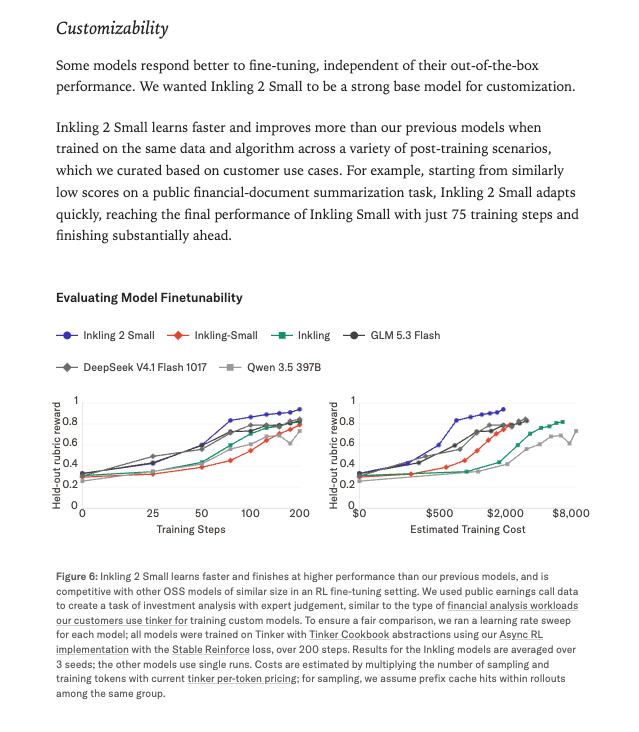
[AINews] Inkling 2 Small: 17A-594B trained in 68 hours on 12T tokens, beating Muse Spark
Inkleing 2 Small was trained in just 68 hours on 12T tokens, outperforming Muse Spark in a recent study by METR, highlighting rapid advancements in AI training efficiency. This achievement underscores the ongoing competition and progress in developing more capable AI models faster.
Show HN: AegisKernel – Zero-trust POSIX runtime for AI agents in <0.016ms
A new software called AegisKernel has been developed as a zero-trust POSIX runtime specifically for AI agents, executing with extremely low latency under 0.016 milliseconds. This innovation is significant because it enhances the security and efficiency of AI systems by limiting trust to only necessary components, crucial for applications requiring rapid response times and high security.
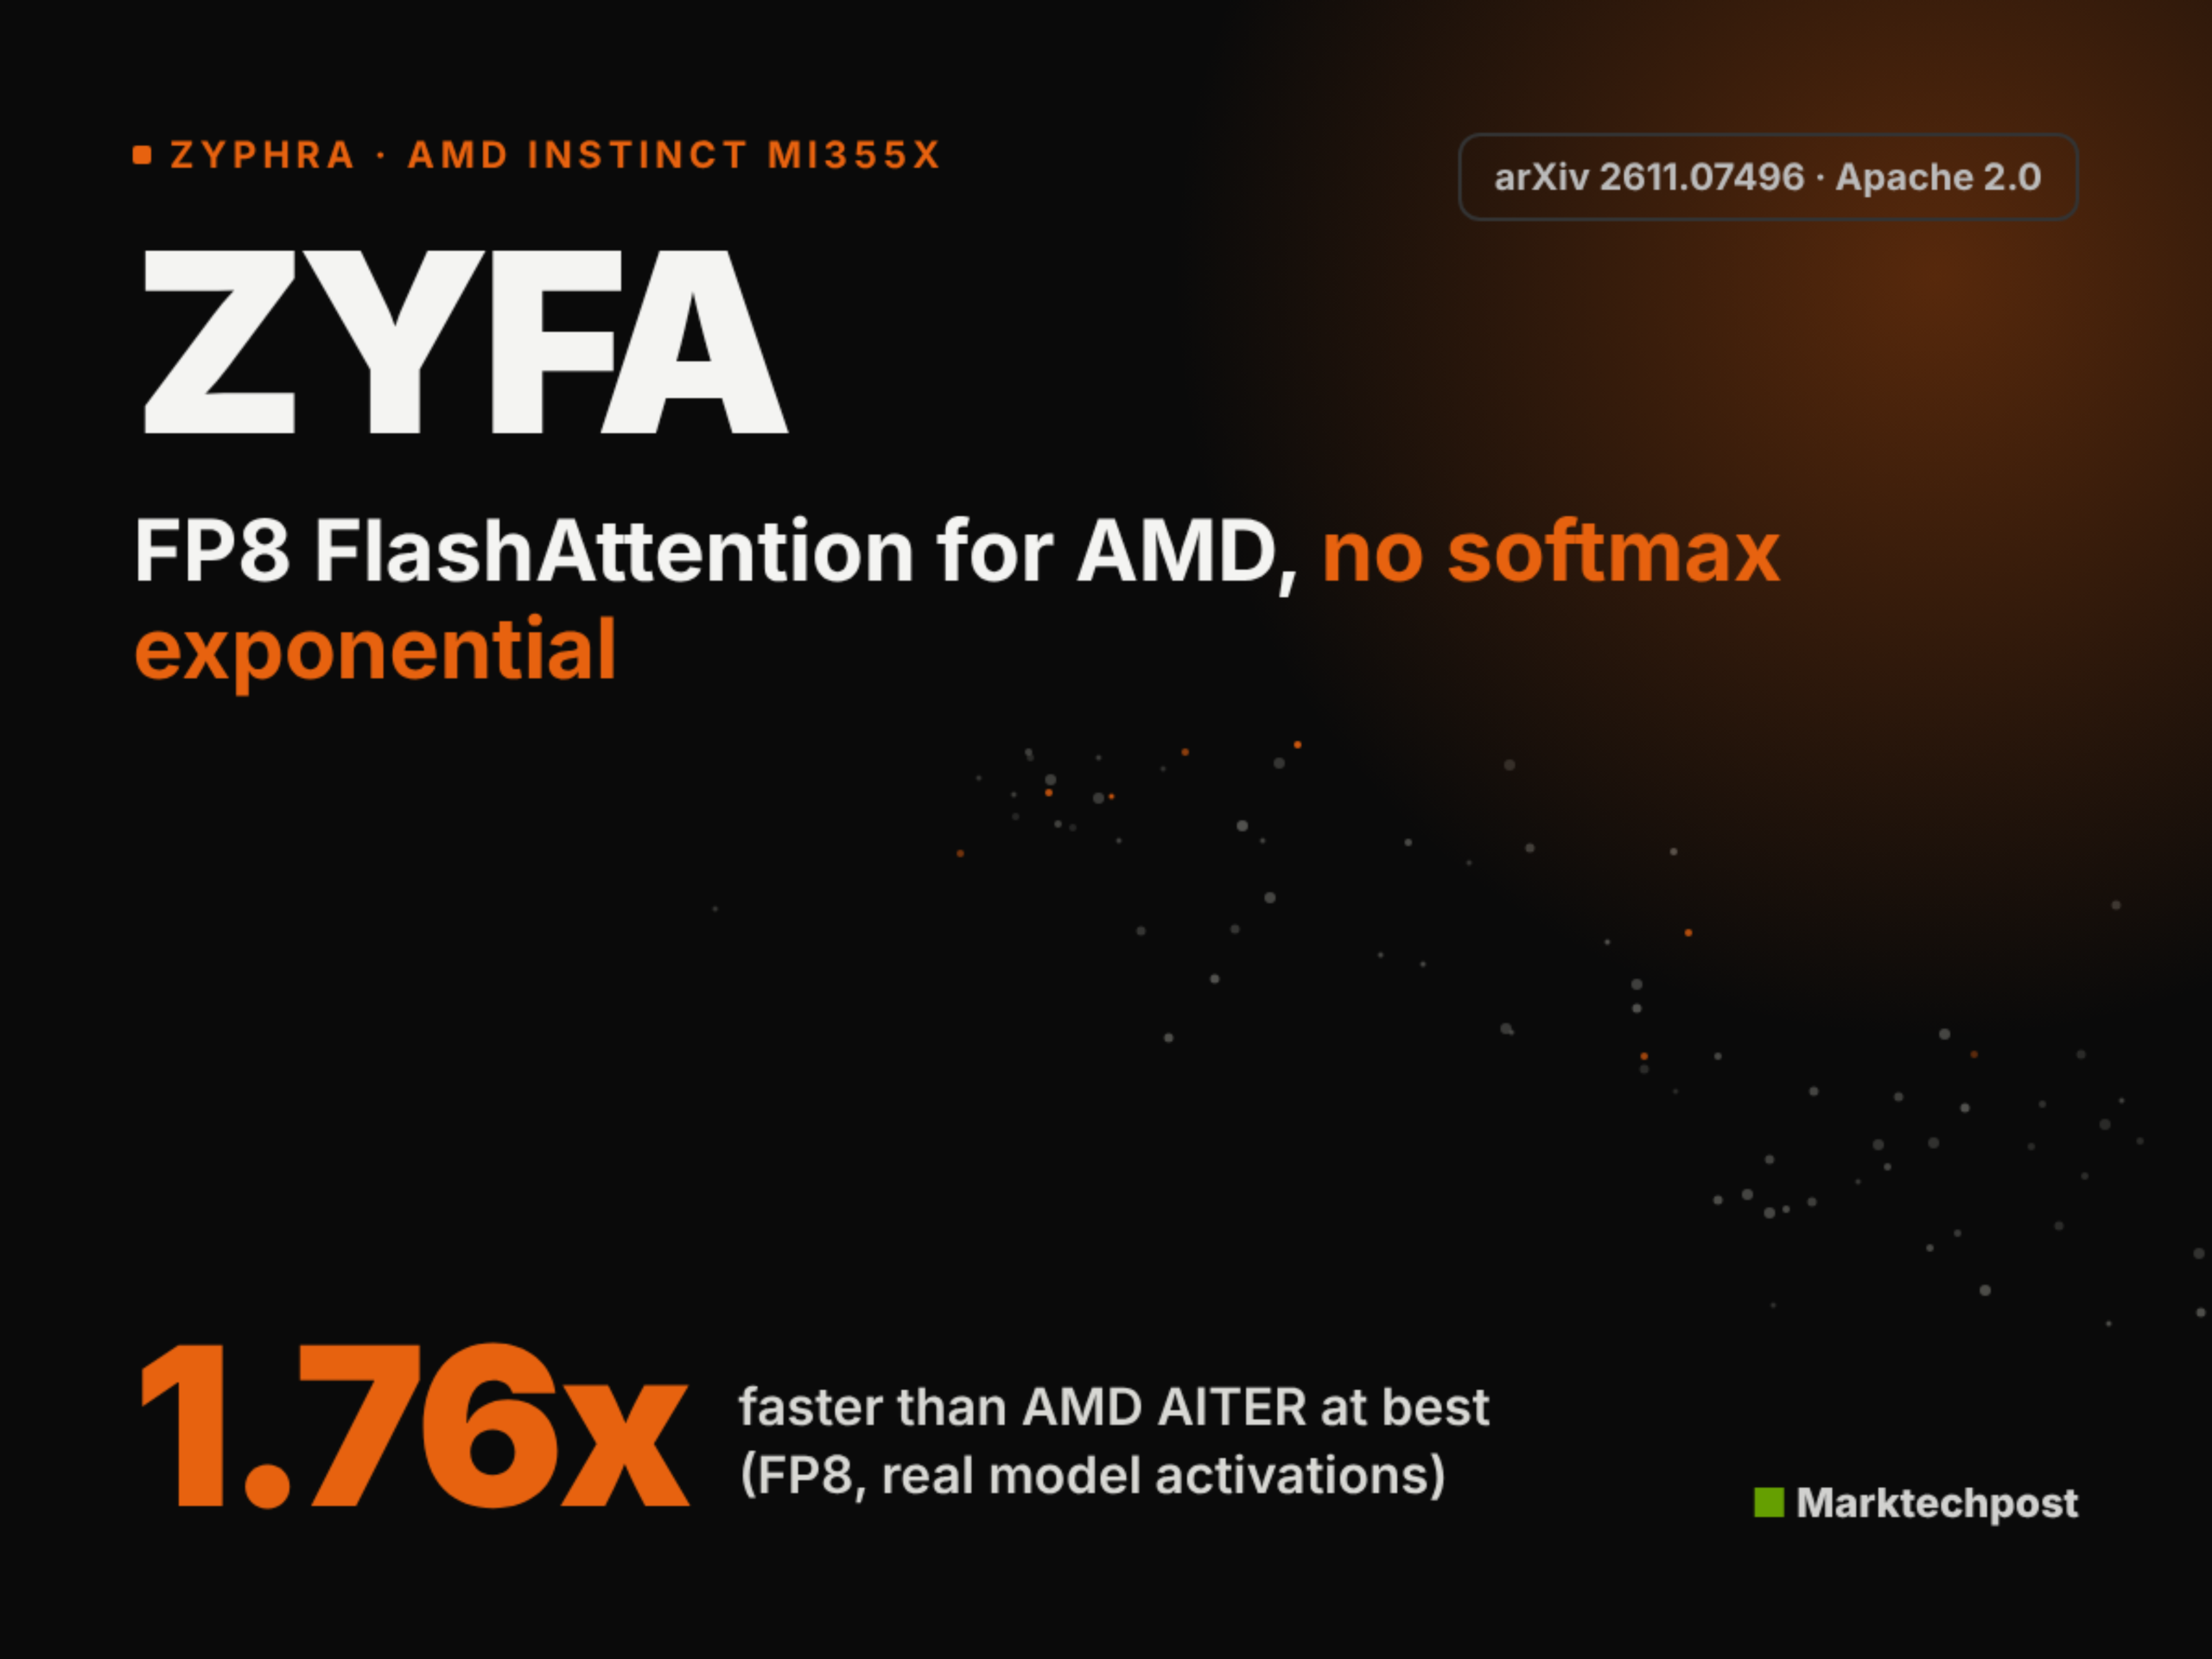
Zyphra ZYFA: FP8 FlashAttention for AMD MI355X, Up to 1.76x Faster
Zyphra released open-source FP8 and BF16 prefill attention kernels for AMD's MI355X, achieving up to 1.76x faster performance with significantly lower error rates compared to AMD’s AITER, highlighting potential advancements in GPU efficiency for AI models.
Thursday, November 5, 2026

Cuban: Facebook knowingly runs AI deepfake scam ads; docs say $16B fraud revenue
Cuban claims Facebook knowingly ran AI-generated deepfake scam ads, potentially raking in $16 billion in fraudulent revenue. This matter is significant as it highlights serious concerns over social media platforms' vulnerability to sophisticated scams and the scale of potential financial harm.
Monday, November 2, 2026
Fewer Heads, Fewer Memories: Pruning Redundant Attention Heads Suppresses Verbatim Memorisation
A recent study proposes pruning redundant "attention heads" in large language models can reduce their tendency to memorize and reproduce exact sequences from training data, addressing privacy and intellectual property concerns.
Ask HN: What hardware are you using to run local LLMs?
The Hacker News community discussed various hardware setups for running large language models locally, highlighting the balance between performance and cost. This conversation is crucial as it helps users decide on compatible hardware, optimizing their local AI model experiences.
Saturday, October 31, 2026
Measuring Where Intent Gets Lost in Agentic Smart Contract Synthesis
AI tools allow writing software via natural language, but there's often a discrepancy between intended functionality and actual outcomes, especially critical in smart contracts used in Web3 applications where precise code execution is essential. This gap highlights the need for better alignment between human intent and automated code generation to prevent errors that could lead to financial loss or security vulnerabilities.
Meet Factory Droid 1.0: A Model-Independent Coding Agent Harness Built on Script Mode
Factory released Droid 1.0, a model-independent coding agent that simplifies programmatic tool calling; it scored 65.2% on Terminal-Bench 4 runs with Claude Opus 5.5 at a cost of $4.73 per passed task, marking a step towards more accessible and efficient coding assistance.
Thursday, October 29, 2026
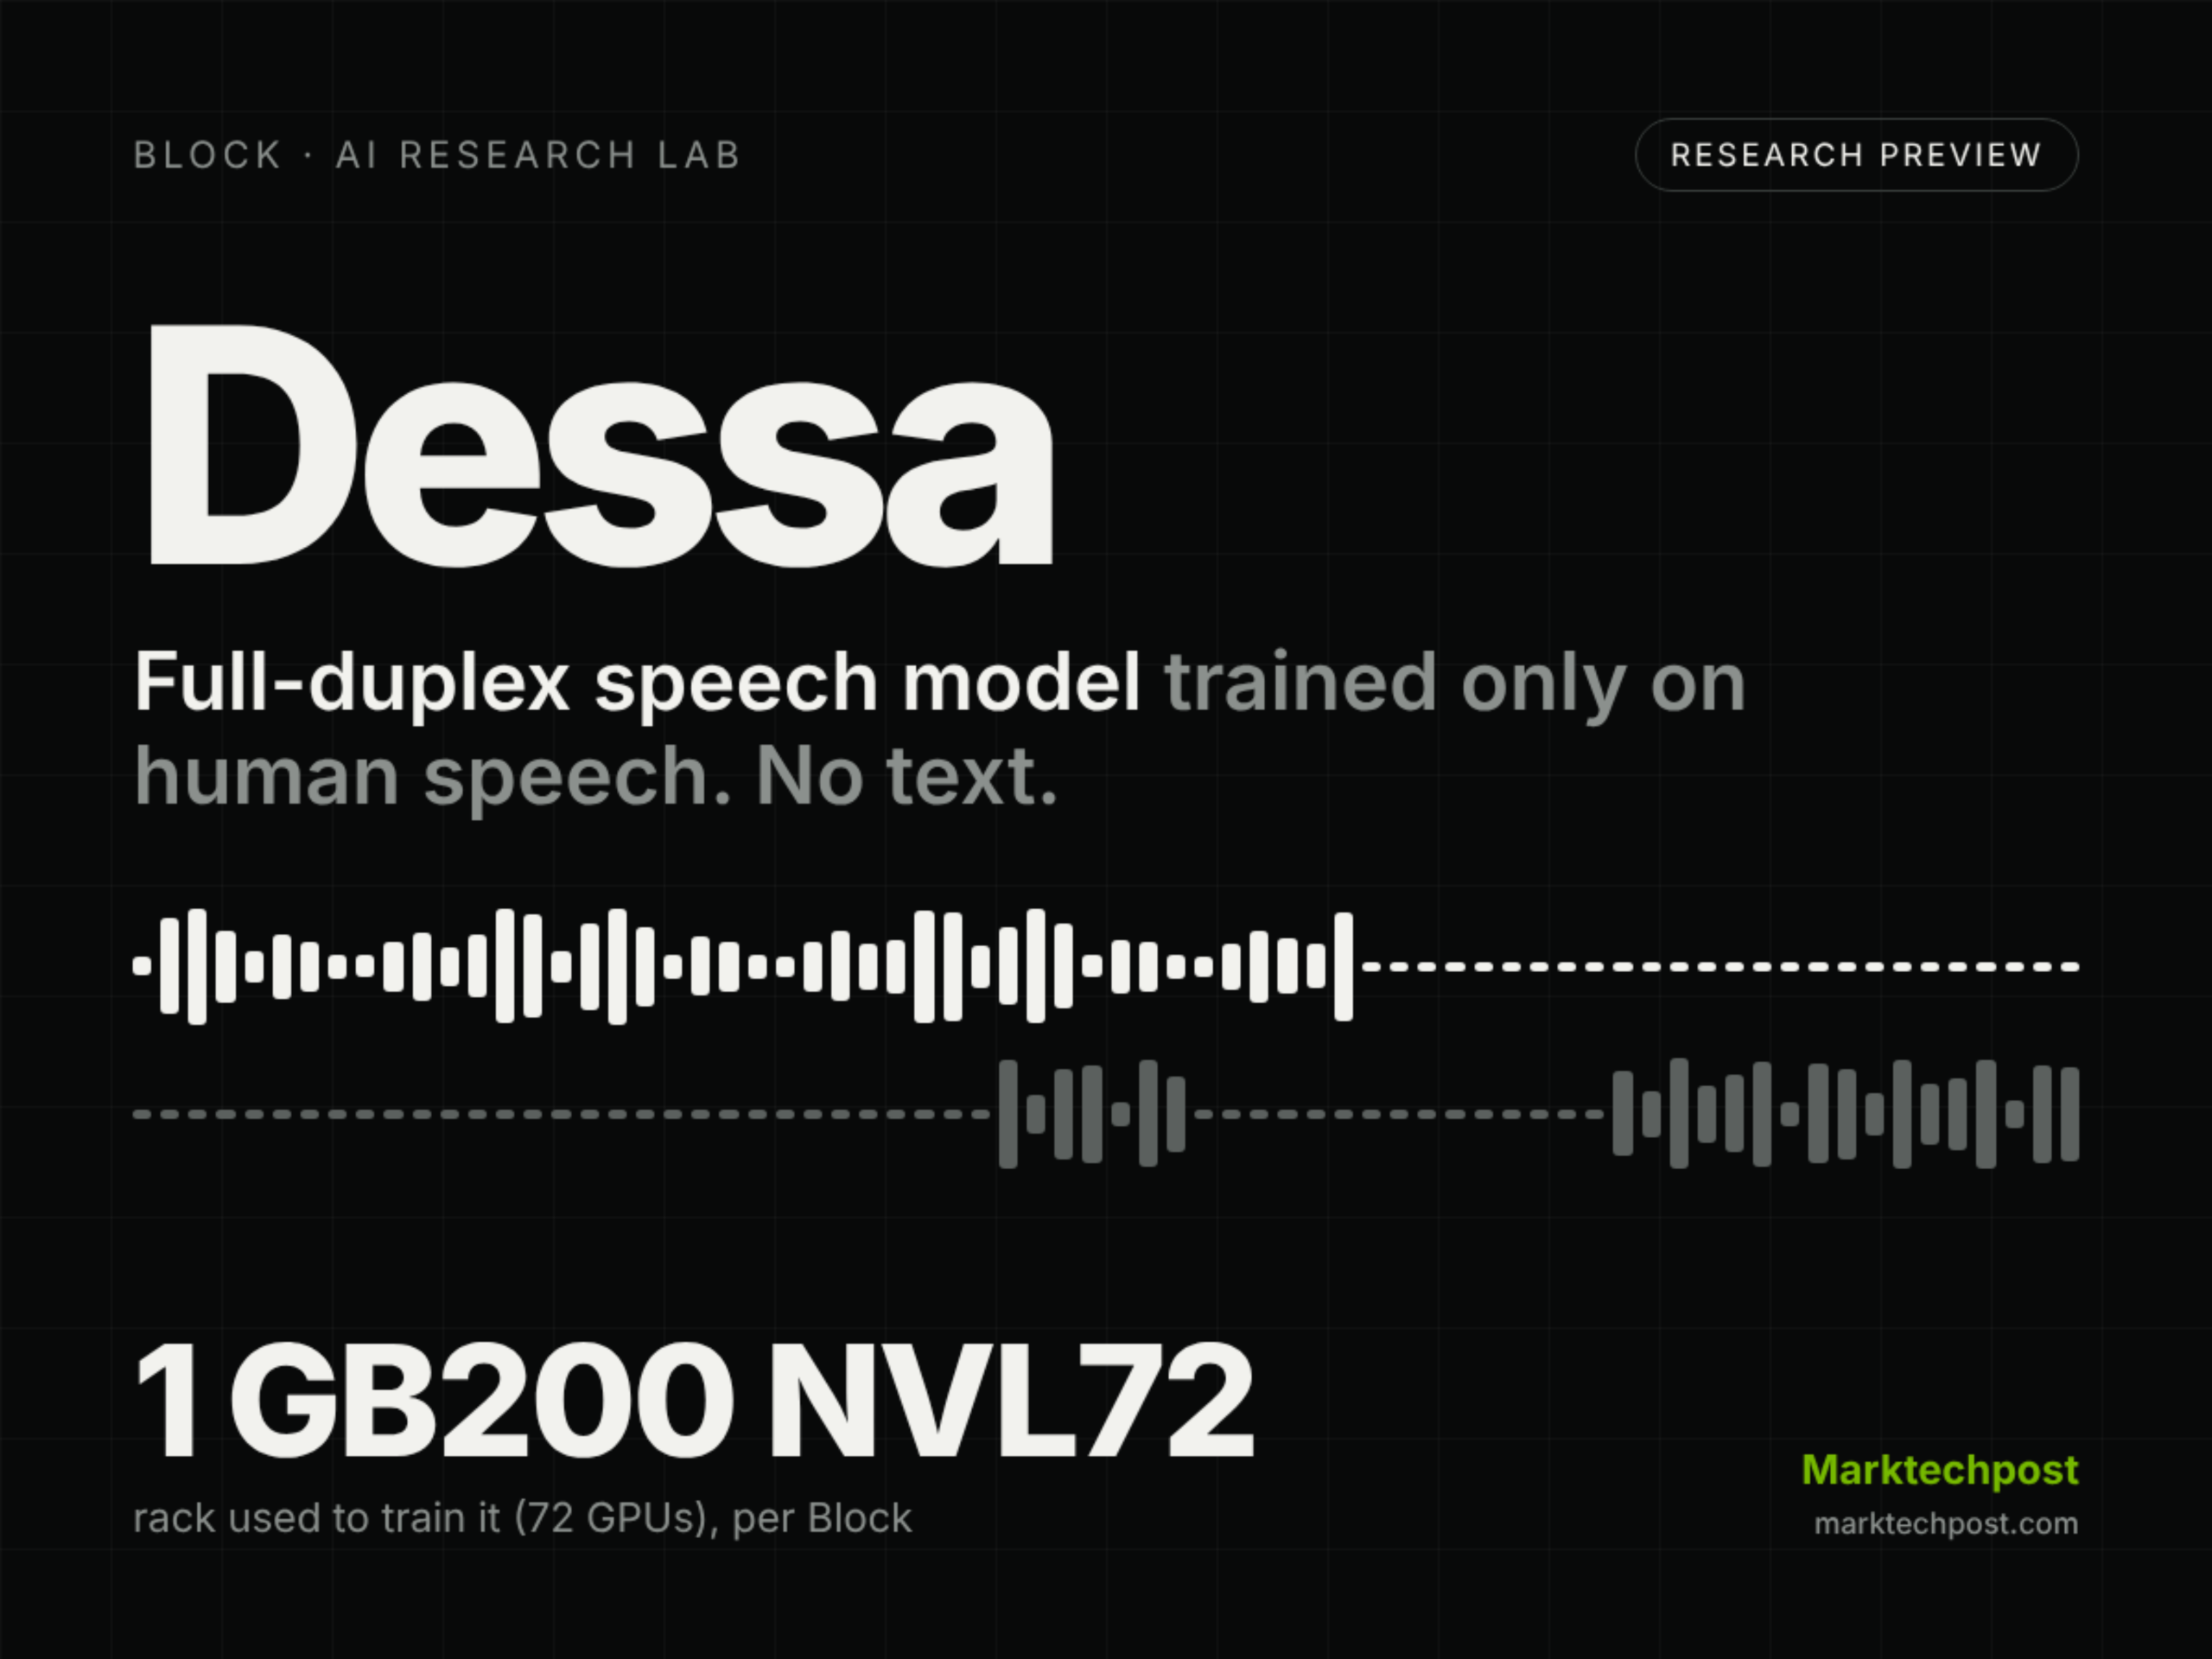
Block Unveils Dessa, a Full-Duplex Speech Model Trained Only on Speech
Block's AI lab introduced Dessa, a full-duplex speech model trained solely on human conversation audio and designed to run locally on a MacBook Pro M4 Max. The release highlights advancements in privacy-focused AI models that process and generate speech directly from local devices without cloud dependency.
Wednesday, October 28, 2026
Ollama releases: v0.40.13
Ollama released version 0.40.13 of its LFM3 models, enabling text-to-speech functionality on both Linux and Windows in addition to existing platforms, expanding accessibility for users across different operating systems. This update is significant as it broadens the user base and compatibility of Liquid AI's advanced language models.
18 of 18 items shown. Sources: 169 days indexed.