Topic: qwen3
7 stories found
Saturday, October 31, 2026
ggml/llama.cpp releases: b12019
The ggml/llama.cpp project updated its codebase to include changes in how the Qwen3-coder handles think blocks, either stripping them or accepting them based on the reasoning_format setting. This update is significant for developers who need to customize the response format of the Qwen3-coder AI model.
Friday, October 30, 2026
ggml/llama.cpp releases: b12000
The ggml/llama.cpp project released version b12000 with support for OCP FP8 E4M3 optimization and fixes in type-checking and data conversion, aiming to enhance performance and compatibility. This update is significant as it improves handling of specific model conversions, potentially boosting efficiency in AI model deployment.
Thursday, October 29, 2026
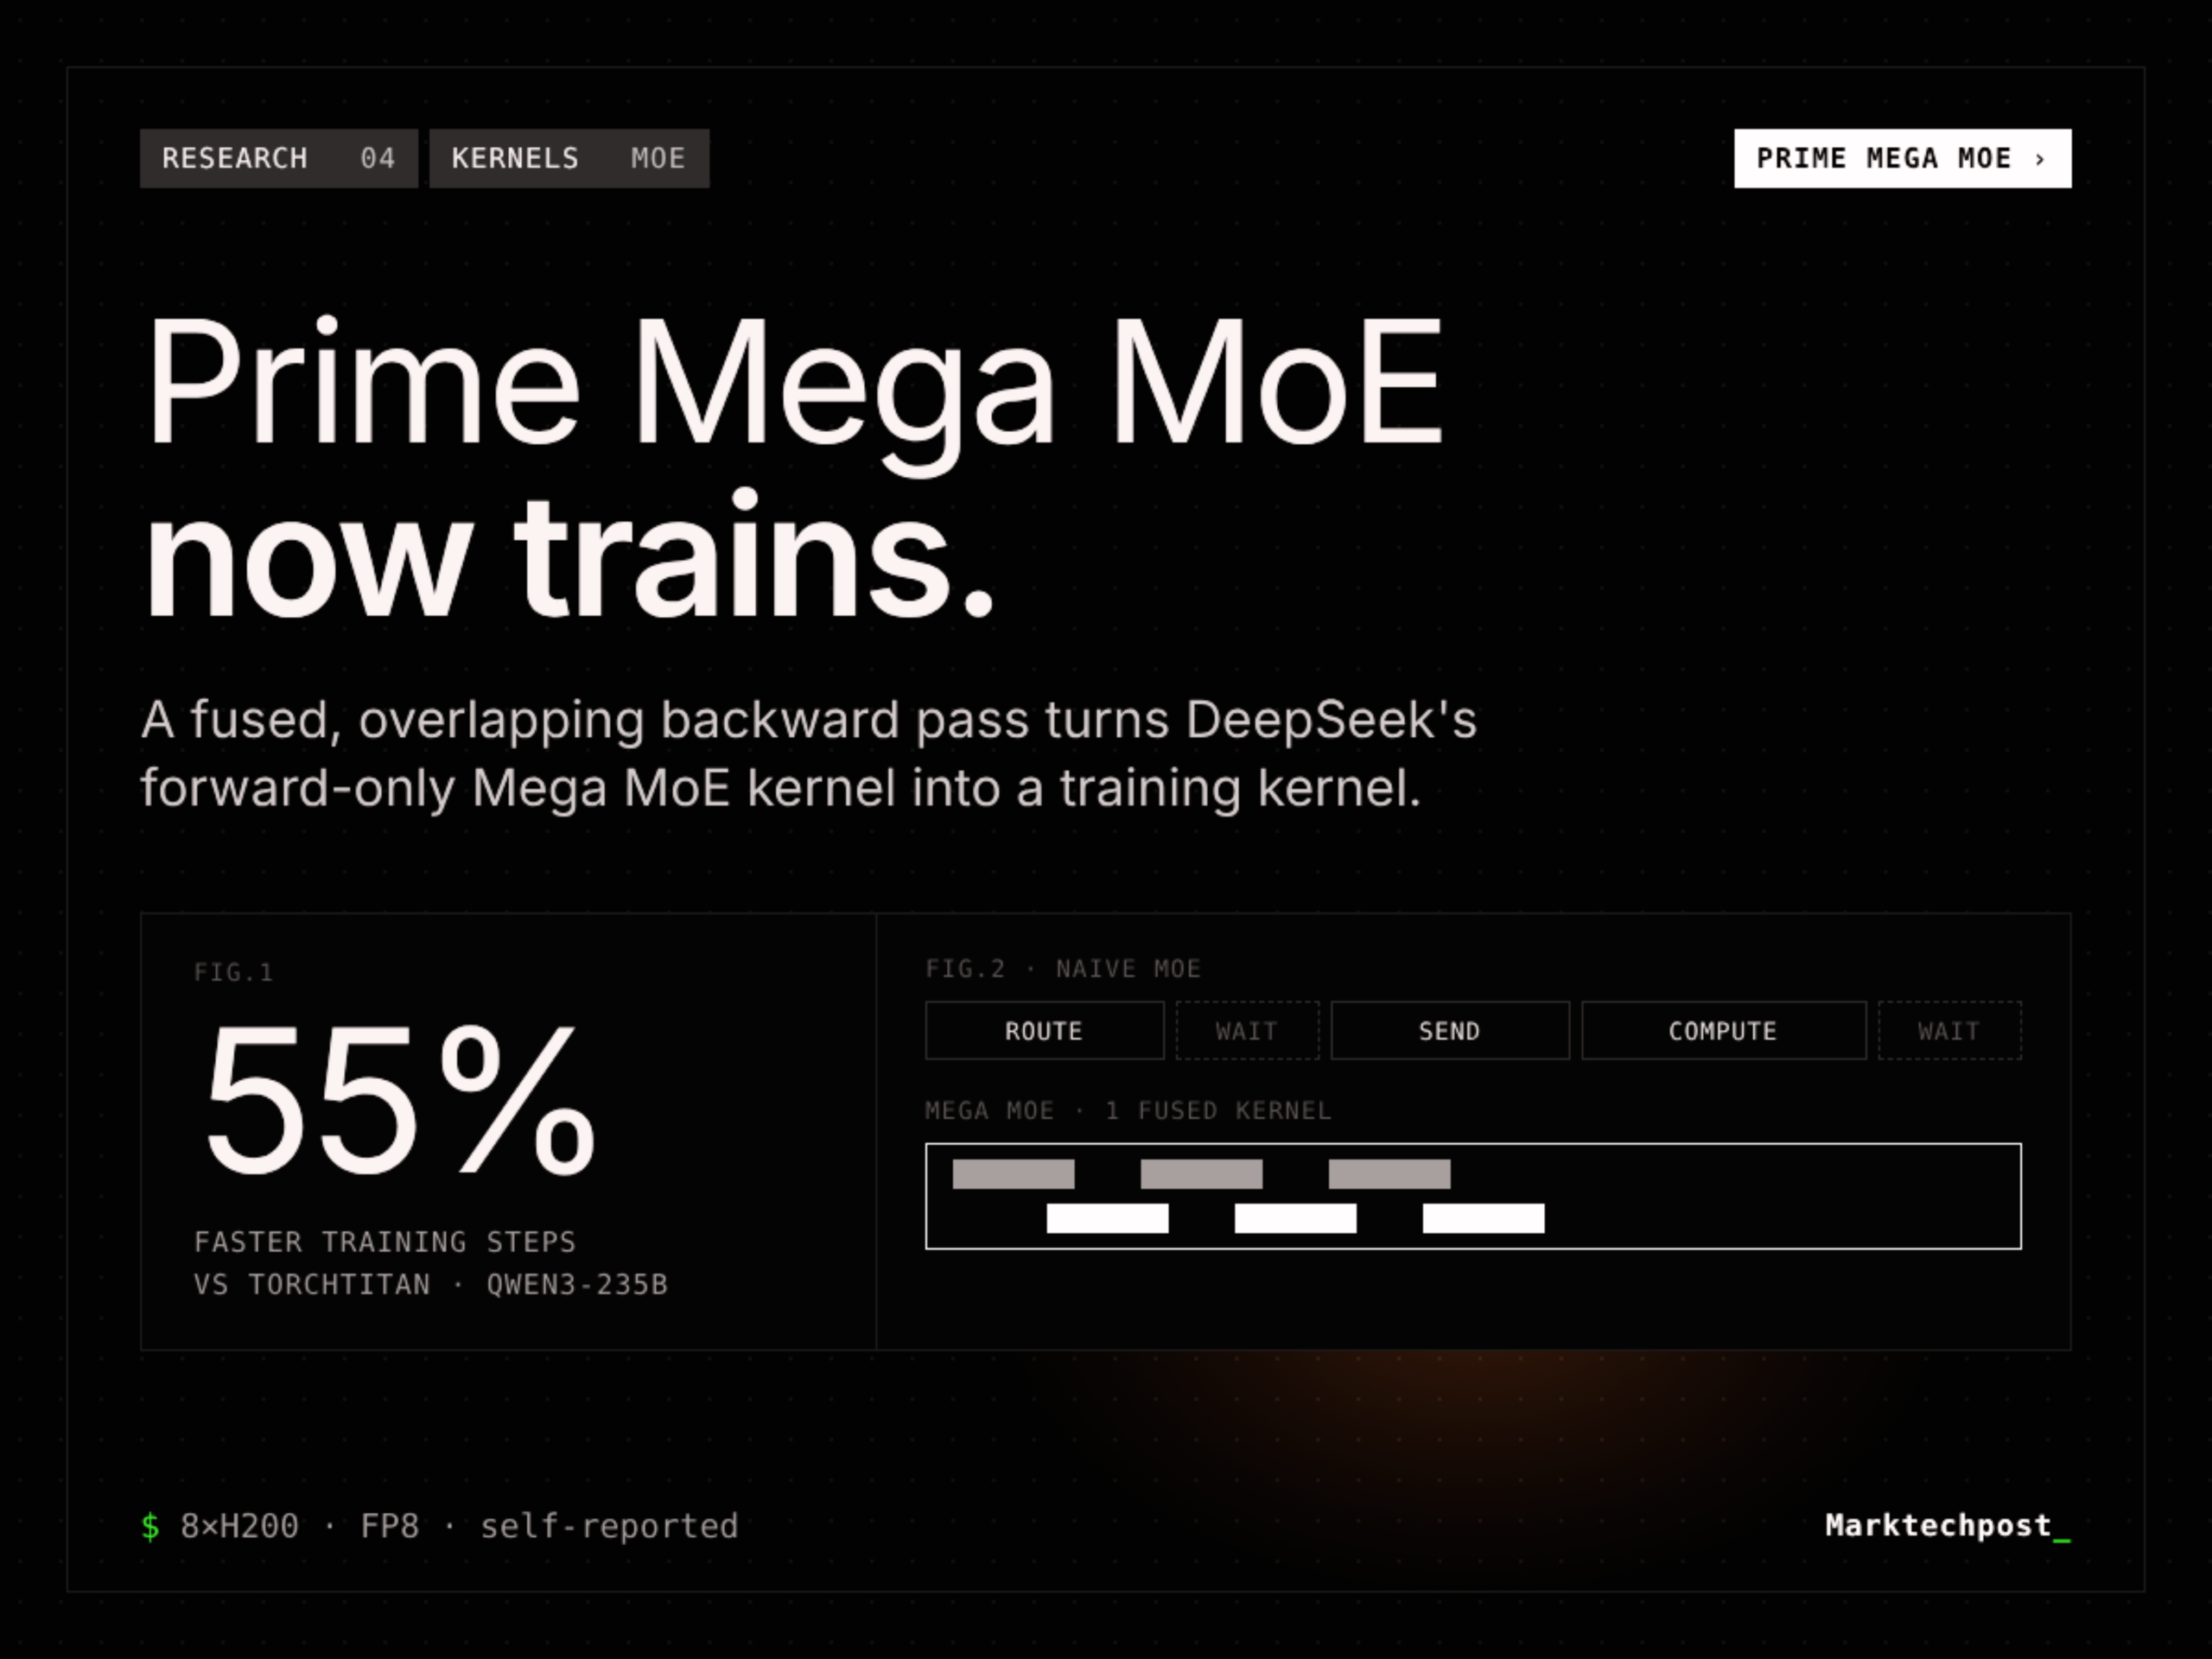
Prime Intellect Releases Prime Mega MoE: Trainable Fused MoE Kernel, 3.11x Faster Forward Pass
Prime Intellect released Prime Mega MoE, a trainable version of the fused Mega MoE kernel that accelerates Qwen3 MoE training by up to 34%, making deep learning model development more efficient.
Wednesday, October 28, 2026

Polymathic AI and Princeton Researchers Release FlashMap, a Flow Map Drafter for 6.14x Faster LLM Decoding
Polymathic AI and Princeton researchers have developed FlashMap, a speculative decoding drafter that can draft 16 tokens in one pass, achieving up to 6.14 times faster lossless speedup on Qwen3-8B, significantly enhancing LLM decoding efficiency.
Monday, October 26, 2026
Transformers releases: Release: v5.21.0
Transformers version v5.21.0 was released, introducing MiniCPM-OCR, a document-understanding model that enhances the suite for processing and interpreting documents, highlighting advancements in AI-driven document analysis.
From Target Selection to Condition Reuse: Auditing Residual Interventions in Tool-Use Models
The study examines whether activation interventions that prompt a language model to generate a specific response also allow the model to appropriately apply intended conditions in subsequent computations, using Qwen3.5-27B for tool-use tasks involving time or permission constraints. This research is crucial for understanding how language models can be guided to use targeted information correctly across multiple steps, enhancing their reliability and utility.
Sunday, October 25, 2026
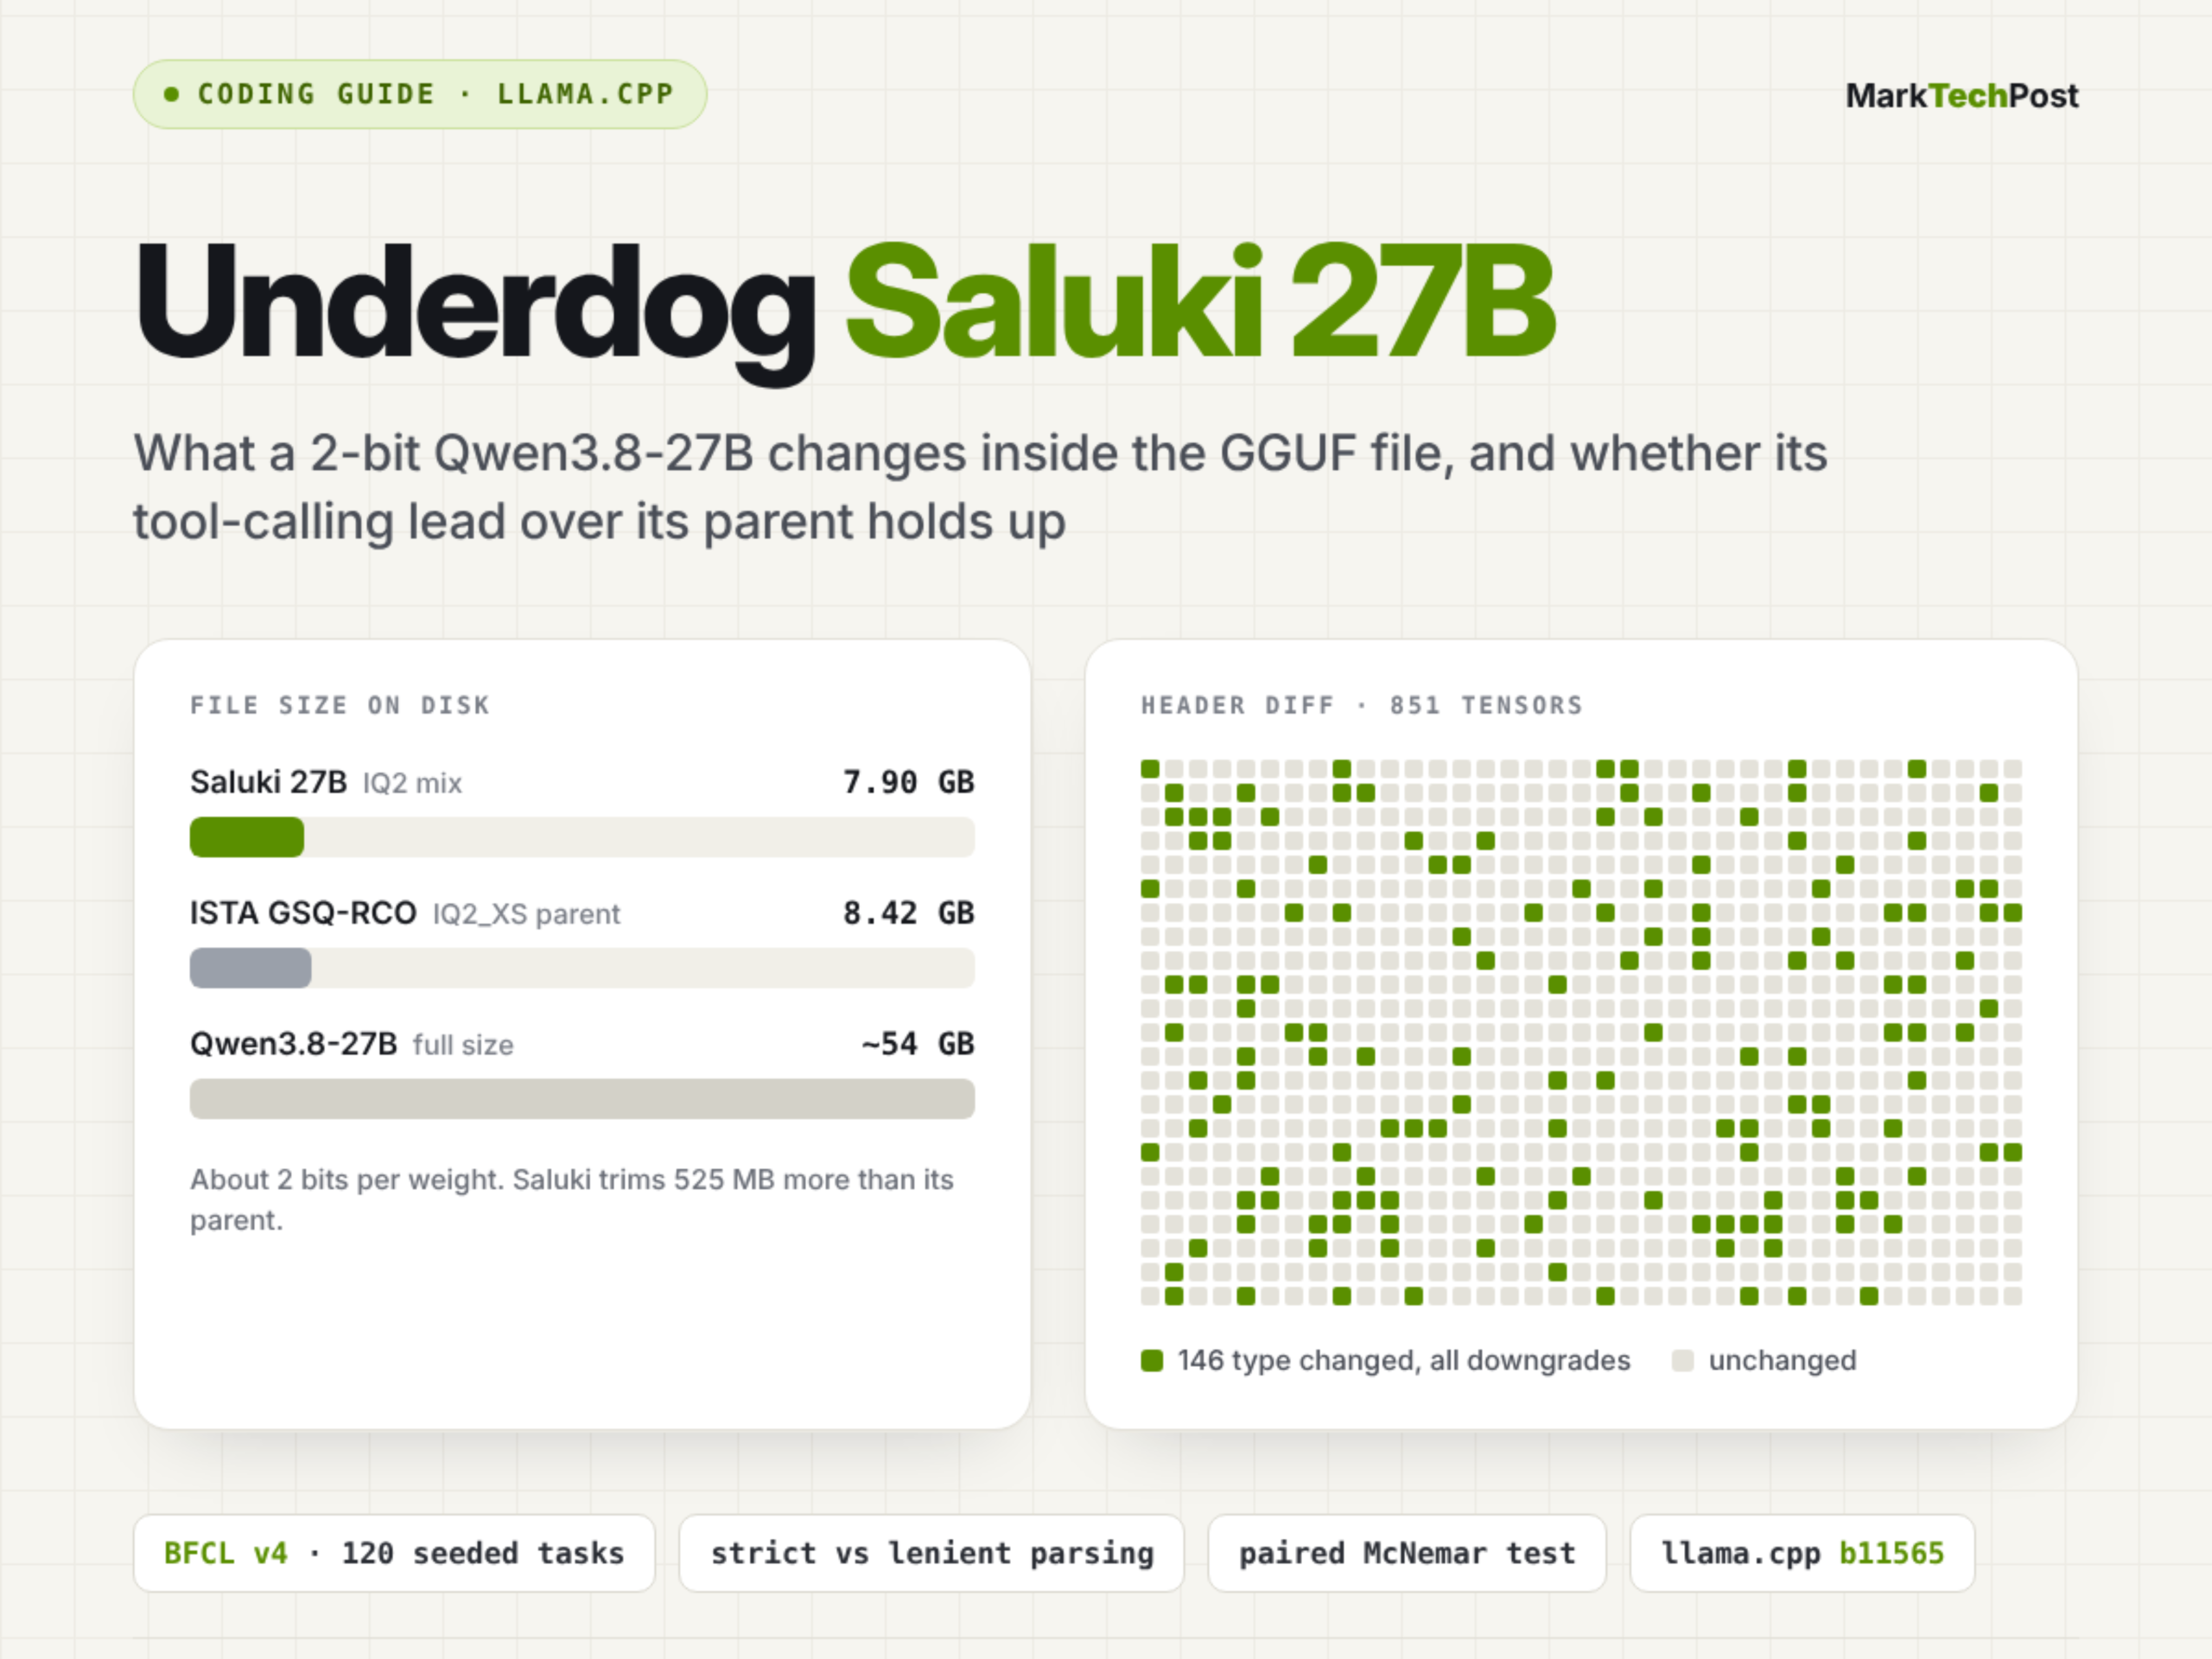
How to Run Underdog Saluki 27B: 2-Bit Qwen3.8-27B Tool-Calling Guide
A coding guide compares Underdog Saluki 27B with ISTA's GSQ-RCO quantization, focusing on GGUF headers, memory usage, and BFCL tool-calling performance in stock llama.cpp. This matters for developers looking to optimize large language models for efficiency and performance.
🌿 That's all for now. Come back tomorrow.
7 of 7 items shown. Sources: 169 days indexed.