industryMarkTechPostOct 29, 2026
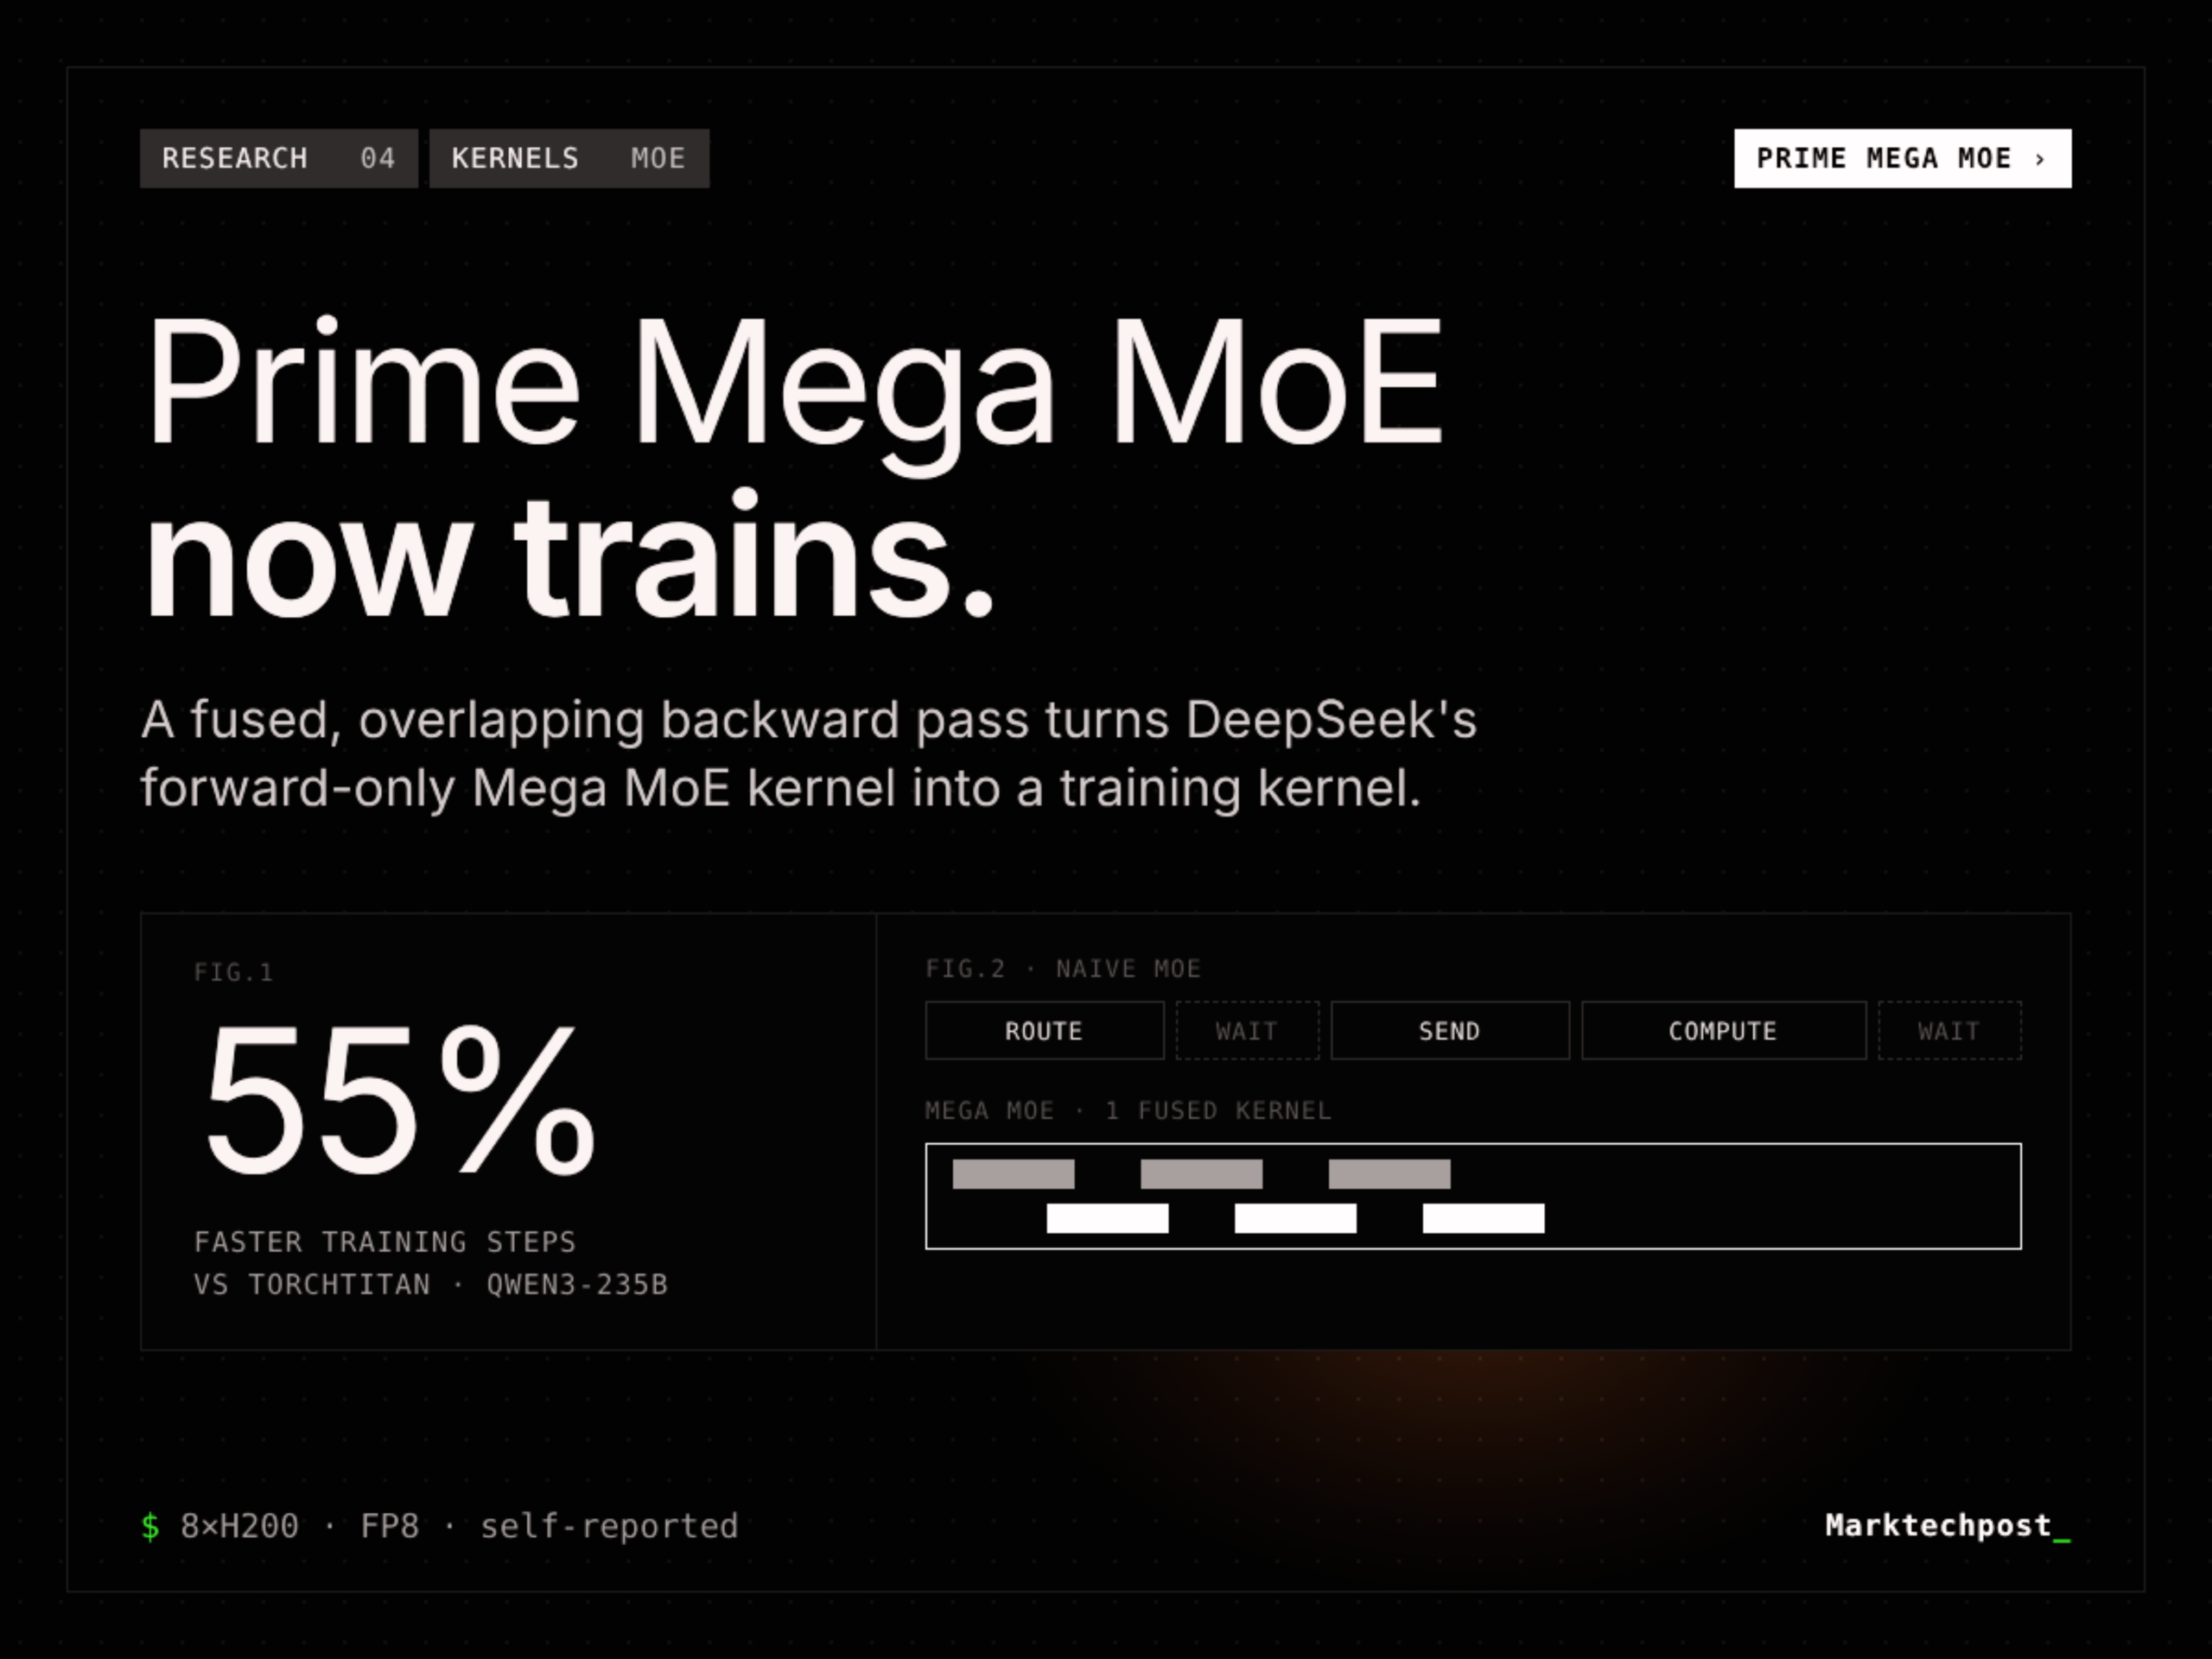
Prime Intellect Releases Prime Mega MoE: Trainable Fused MoE Kernel, 3.11x Faster Forward Pass
 Read original ↗
Sentiment: positive
TL;DR
Prime Intellect released Prime Mega MoE, a trainable version of the fused Mega MoE kernel that accelerates Qwen3 MoE training by up to 34%, making deep learning model development more efficient.
Detailed Summary
Prime Intellect released Prime Mega MoE, a trainable fused Megatron-MoE kernel that accelerates the forward pass by 3.11 times, significantly reducing Qwen3 MoE training steps. This update is part of DeepSeek’s suite and was showcased in prime-rl, demonstrating up to a 34% improvement in backward pass efficiency. The broader impact includes enhanced performance and reduced computational costs in large language model training.
Key Points
- • Prime Intellect released Prime Mega MoE.
- • It is a trainable fused Mega MoE kernel.
- • Speeds up forward pass by 3.11x.
- • Enhances Qwen3 MoE training steps by up to 34%.